
Show your ad to a thousand people before you show it to anyone.
Mimic builds a population of AI agents that browse, think and buy like your audience, runs your whole flight past every one of them, in order, and shows what each creative and channel contributed. Rehearse it. Then run it.
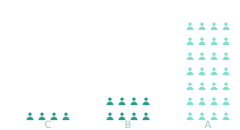
Three creatives. Same population. Ranked.
Same audience, same budget, same channel. Only the copy changes.
See who your ad actually reaches.
One population, four ways to look at it. The figure is the same crowd every time; the tab changes what it is showing you.
Your creative, shown to every agent.
Give Mimic the ad as it will run: the image, the headline and body, or the email. Each is scored on seven persuasion parameters, per audience, then shown to every agent in the population. Watch the same thirty agents see three creatives in turn: the strong image reaches most of them, the neutral copy a third, the email somewhere between. Same audience, same budget, same channel; only the creative changed.
The same ad lands differently by tribe.
Switch the lens and the crowd sorts into tribes. Two of them take the message readily; the others hardly hear it. That is per-segment scoring: a skeptical deliberator and an impulse buyer do not read the same ad the same way.
Each channel reaches a different crowd.
One flight, one population. Every channel runs against the same crowd, and each exposure carries over into the next. Social spreads through the network. Search lights up the few who were already looking. Email and display reach a scattered set once. Mimic reports what each channel contributed to the flight, not what it would have done on its own.
What the population did, in numbers.
Impressions, clicks, conversions, CTR, CVR, revenue, ROAS and CPA per channel, plus a conversion curve over the campaign duration. The curve traces the same timeline the animation just played.
Three steps. No setup, no data, no pixel.
Most marketing tools need a month of campaign history before they say anything useful. Mimic only needs a description of the campaign you plan to run.
-
1, about a minute
Describe the campaign
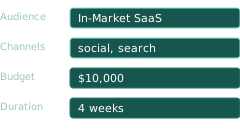
Pick an audience and your channels, set budget and duration, paste your copy or upload the ad. Nothing to install, nothing to connect.
-
2, automatic
Mimic builds the population
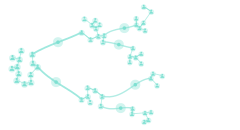
Thousands of agents, each with its own personality, habits and place in a network. Every ad in your flight passes through four stages inside each agent: attention, processing route, feeling, decision. Fatigue, awareness and attitude carry over to the next ad, and agents influence each other, so the crowd behaves like a crowd.
-
3, under 5 seconds
Read the results
CTR, conversions, revenue, ROAS and CPA per channel, what each creative contributed in the position it ran, and a ranked list of what would move the response.
Your audience is not an average. It is a population.
Other tools give you a segment average: one number standing in for a million people. Mimic shows your ad to every agent, each decides for itself, then talks to the agents near it, the way real audiences do. The result is what the population did, not what a formula assumed it would do. Every agent is synthetic; no data about a real person enters the system.
Straight answers, labeled honestly.
Claims carry the same labels as in the product. Verified means checked by our automated protocol. Modeled means a model assumption you should check against your own numbers. Illustrative means an example, not an engine output.
The basics
What is Mimic?
A campaign simulator built on AI agents. You describe the campaign (audience, channels, budget, duration, and optionally your real ad copy) and Mimic generates thousands of individual synthetic buyers, runs your whole flight past them in order, and shows you what happened: CTR, conversions, revenue, ROAS, and CPA per channel, plus what each creative contributed in the position it ran.
Each simulated buyer has an individual personality, behavioral profile, channel preferences, and a position in a social network, and responds to your creative according to established behavioral-science models rather than a black-box average.
How long before I get my first result?
About a minute to describe the campaign, under five seconds for the engine to return the results. There is no pixel to install, no historical data to upload, and no ad account to connect.
This is the practical difference between Mimic and an analytics tool: analytics needs a month of your spend before it can say anything. Mimic works on a campaign you have not run yet.
How does the free week work?
Seven days of full access to the whole engine. Checkout collects your card up front but charges nothing during the trial. Cancel at any point in those seven days and you are never billed. If you stay, billing starts on day eight at $50/month, and that founding rate is locked for as long as you stay subscribed.
Cancelling is one click in the Stripe billing portal, the same place you signed up. No email, no retention call.
How is this different from other ad tools?
Benchmark tools tell you what the average advertiser saw. Mimic models your combination of audience, creative, and channel mix against a population of individual agents rather than a segment average. The same ad copy produces different results for different audiences, because each audience processes persuasion differently. That is a deliberate, tested property of the engine, not a side effect. Verified
What science is it built on?
The behavioral core rests on published, peer-reviewed foundations. Personality uses the Big Five framework (Costa & McCrae, 1992), and persuasion processing follows the Elaboration Likelihood Model (Petty & Cacioppo, 1986).
Audiences and creative
Which audiences can I simulate?
The catalogue contains 92 audiences across three libraries:
| Library | Count | Categories |
|---|---|---|
| Behavioral archetypes | 5 | Tech early adopters, value seekers, brand loyalists, socially driven, impulse buyers |
| Google Ads | 54 | In-Market, Affinity, Life Events, Detailed Demographics |
| Meta Ads | 33 | Interests, Behaviors, Life Events, Demographics, Custom & Lookalike |
Each audience is an 18-parameter psychographic profile. The Google and Meta presets mirror the audience types you would actually buy on those platforms, so a result maps directly onto a real media plan.
Do I have to provide ad copy?
No. Leave it blank and Mimic models a neutral creative, which is useful for comparing audiences and channels on a level playing field.
Providing your real headline and body text is where the tool earns its keep, because creative quality drives large, realistic swings in the results. In verification, an identical ad moved from 0.45× ROAS with a neutral creative to 4.1× with a strong creative (a clear offer plus proof), roughly a 9× swing from copy alone. Verified
How is my copy scored?
On seven persuasion parameters (salience, value proposition, argument quality, source credibility, clarity, relevance, and emotional tone), scored per audience, because the same ad lands differently with a skeptical deliberator than with an impulse buyer.
The language model that reads your creative runs that rubric several times and keeps the median for each parameter. If a parameter's scores scatter across passes, it is flagged inside the engine as unreliable instead of dressed up as a confident number. The scores are then frozen and drive every exposure in the flight. If the model endpoint is degraded or unavailable, a fixed-rule local scorer takes over and the interface tells you which scorer produced your numbers.
Which channels are supported?
Five: social media, email, display, search, and influencer. All five run in one flight against the same population, so an exposure on one channel carries over into the next. The results show each channel's attributed contribution to the flight.
Results and money
What do I get back from a simulation?
Headline KPIs (impressions, clicks, conversions, CTR, CVR, revenue, ROAS, CPA), a per-channel breakdown, and a conversion curve over the campaign duration.
How does budget turn into impressions and revenue?
Through a transparent cost bridge. Your budget converts to impressions using per-channel effective CPMs, and conversions convert to revenue using a value-per-conversion figure you set yourself.
Two CPMs are sourced from 2025 industry benchmarks: social/Meta feed at $13.48 (Triple Whale, 2025) and display at $2.80 (WordStream GDN report). The remaining three (search, email, influencer) are Mimic's own assumptions and are labeled as such in the product. Modeled ROAS and CPA follow the standard definitions in Farris et al., Marketing Metrics.
Accuracy and trust
How do you know the simulation isn't just noise?
It is verified against a pre-registered two-platform calibration protocol: a fixed neutral creative is delivered to every audience, and the simulated click-through ranking is correlated against each audience's known propensities. Audiences that should click more do click more in the simulation, and creative quality measurably moves outcomes. Verified
Are the results guaranteed to match my real campaign?
No, and we won't pretend otherwise. The verification above establishes internal believability: differentiated, propensity-ordered, literature-consistent outputs, verified in simulation. Absolute real-world accuracy, meaning whether your ad hits exactly this CVR, can only be settled by live field data, and empirical field calibration is part of the ongoing program. We've set a specific bar before we'll say otherwise: simulated results have to rank-correlate with live results at 0.7 or better, on two ad platforms. We'll publish the validation when we have it.
Treat the results as a planning and comparison tool (which audience, channel, and creative should I bet on, and roughly what should I expect), not as a guarantee of specific dollar outcomes.
Will two runs with the same inputs give the same result?
Close, not identical. A simulated crowd has randomness in it, the same way a real one does, so two runs with the same inputs land near each other rather than on the same number. Read it the way you'd read any test: a small wobble between runs is noise; a difference that holds up when you change one input and rerun is a signal worth taking into the planning meeting.
Every input is yours (creatives, audience, channels, budget), so when a result moves you can trace it back to something you changed.
Does Mimic use my customers' personal data?
No. Every simulated buyer is synthetic, and every simulated response is generated from our proprietary audience profiles and cognitive architecture, not from tracking data, purchased data, or any individual's records. Nothing about real people enters or leaves the system.
How is quality controlled?
The engine ships with a 101-test automated harness covering every layer: audience schema integrity, population verification (a generated crowd is checked against its own segment-mix, behavioral-mean, and trait-correlation targets), action-model properties, targeting math, and end-to-end smoke tests. Alongside it runs a standing calibration script that re-runs the two-platform protocol against the engine. Verified
Model boundaries, current version
One audience per run
Each simulation uses a single audience. Compare audiences by running the flight again with a different one.
Budget is split evenly across the channels you select
Weighting spend by channel is not in this version. Test a channel mix by adding or removing channels and rerunning.
The population is a fixed sample scaled to your budget and media costs
Reach figures scale with budget; the composition of the crowd does not.
Field accuracy is not yet proven
Behavioral weights come from the published persuasion literature, not from calibration against live campaigns. Our bar: rank correlation of 0.7 or better with live results on two platforms. Until then, treat the output as a structured simulation, not a measurement.
Sex and geography are reach filters, not behavior modifiers
They change who is reachable and how many, but not how the simulated population behaves. Behavioral deltas by sex and geography are a v2 item.
Local geography narrows audience size, not composition
Fine-grained local geography narrows the audience size estimate, but the behavioral model runs at national composition in this version.
Three of five channel CPMs are model assumptions
Search, email, and influencer CPMs are not sourced benchmarks. Check them against your own media costs before relying on the money figures. Modeled
DMA coverage is the top 25 markets
Per the Nielsen Local TV Report 2024–25, with an expansion path to all 210 markets.
We would rather you read these here than discover them later. Questions not covered? help@simulacraai.io
See Mimic run your next campaign.
Book a live walkthrough. Bring the ads you plan to run and watch the population respond.
Book a demo- Live walkthrough
- Bring your own campaign
- No setup or data needed